
Getting Started#
Core Concept#
Automatically send data and model files to the systems that need them
In AI workflows, a wide range of files—including raw data, preprocessing results, training data, model files, and inference results—are used across multiple systems and environments.
By connecting where each file is created with the system that uses it, you can send data to the next processing environment as soon as it is ready, then route generated models and result files to the locations where they are needed.
- Data Source
- Data Processing
- AI Training
- Model Output
- Result Storage

With this setup, AI data and model files can be managed according to the processing environment at each stage, with each file automatically flowing into the next task as soon as it is ready.
Workflow Flow#
Connecting the workflow from data collection through processing and result utilization
Collect data generated across multiple systems and send it to the AI processing environment where it is needed.
Once data processing and training are complete, send the generated models and result files to the next system or storage environment for downstream use.
Each stage can use the files and processing results generated by the previous stage as inputs for the next stage.
Automation Benefits#
Reduce repetitive large-file movement and management at every stage
As AI workloads grow in data volume and processing stages, the work required to prepare files and send them to the systems that need them grows as well.
By configuring the next task to run automatically based on file creation and processing status, you can connect each stage's file flow in a defined sequence.
| Category | Manual File Management | Workflow Automation |
|---|---|---|
| Data Collection | Check files on each system | Collect data from multiple systems into a single workflow |
| Processing Environment | Prepare files for the next system | Automatically send files to the required system based on processing conditions |
| Model Management | Check generated model files | Route models to the designated environment after generation |
| Result Utilization | Prepare processing results for the next task | Automatically connect result files to the next task |
This lets you define the flow of data, models, and result files stage by stage and manage the entire AI workflow as a single file workflow.
IT Engineer#
Configure an automated workflow for AI data and model files
Data Collection#
Bring data from multiple systems into a single workflow
First, connect the systems where data for AI processing is generated or stored to the workflow.
Set each system's file paths and collection targets to bring data from multiple locations into a single processing flow for use in the next stage.
[Product UI: Flow Canvas screen connecting multiple Source systems and data folders to a single data collection task]
If needed, set conditions such as file paths, names, and extensions to collect only the data required for AI processing.
Processing Connection#
Send collected data to the AI processing systems that need it
Once the collected data is ready, connect it to the AI processing systems that perform the next tasks, such as preprocessing, training, or inference.
Specify the systems and file paths used at each processing stage, and configure the output from one stage to become the input for the next system.
- Collected Data
- Preprocessing
- Training Server
- Inference / Analysis
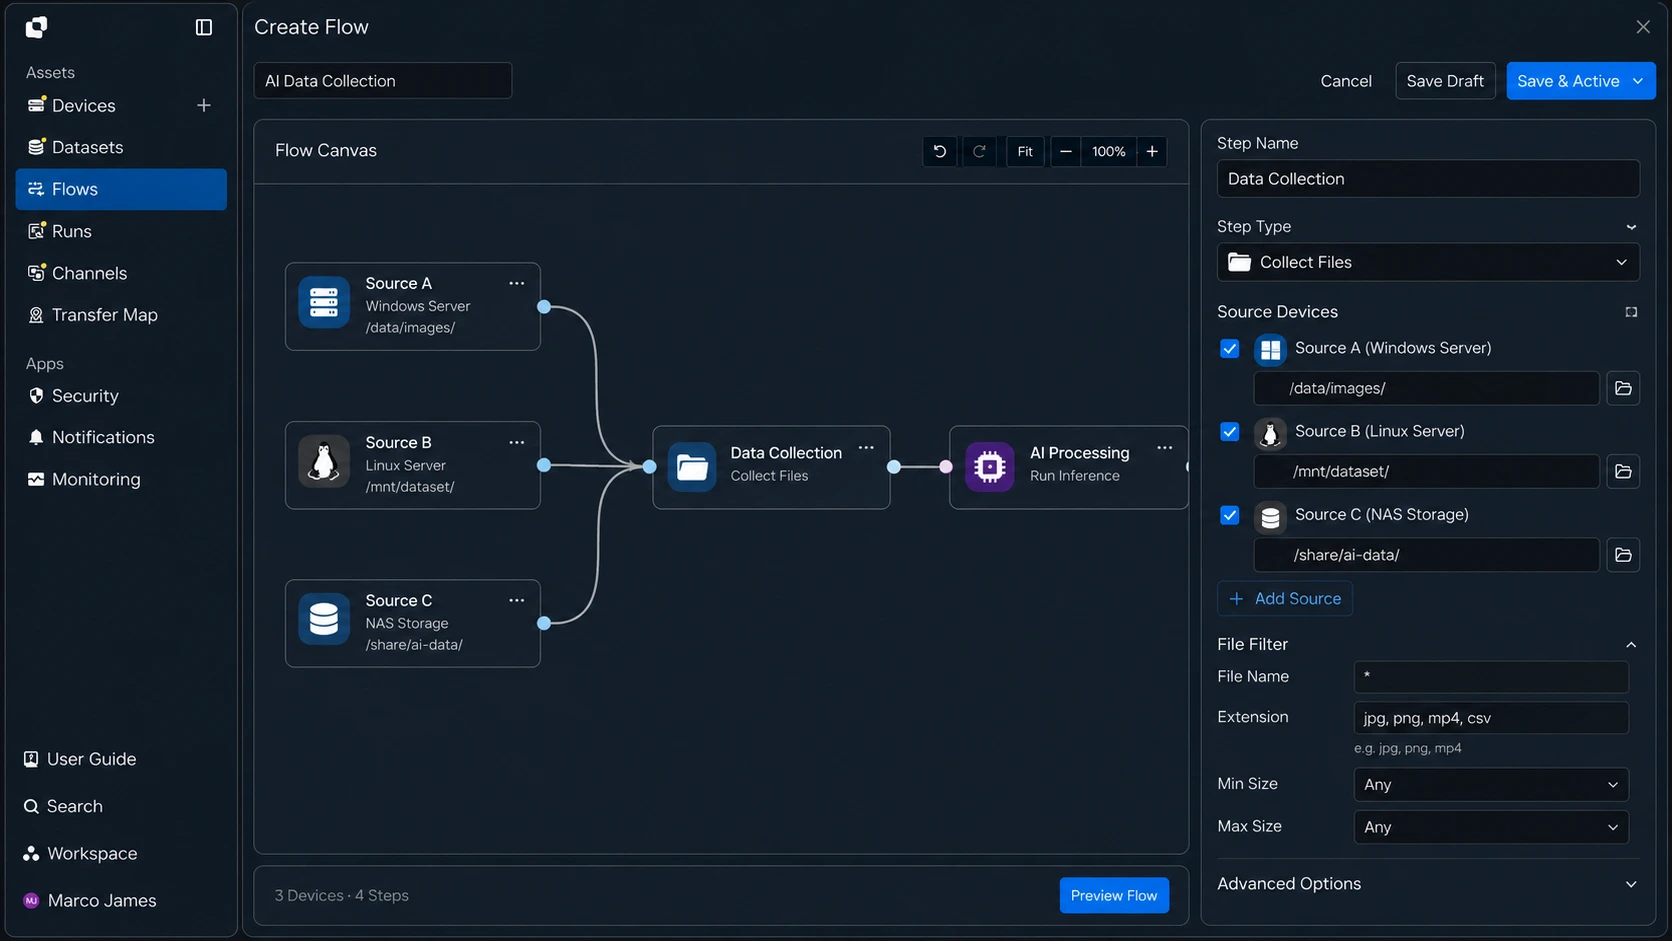
With this setup, the files required at each AI processing stage can be automatically sent to the prepared working environment.
Job Conditions#
Start the next task based on data and processing status
Each workflow stage can be configured to start the next task when a defined condition is met, such as file creation, completion of data collection, or completion of processing.
For example, you can start preprocessing once data has been collected from multiple systems, then continue to the training task as soon as the preprocessing results are generated.
- Data Ready
- Collection Complete
- Start Processing
- Processing Complete
- Start Training
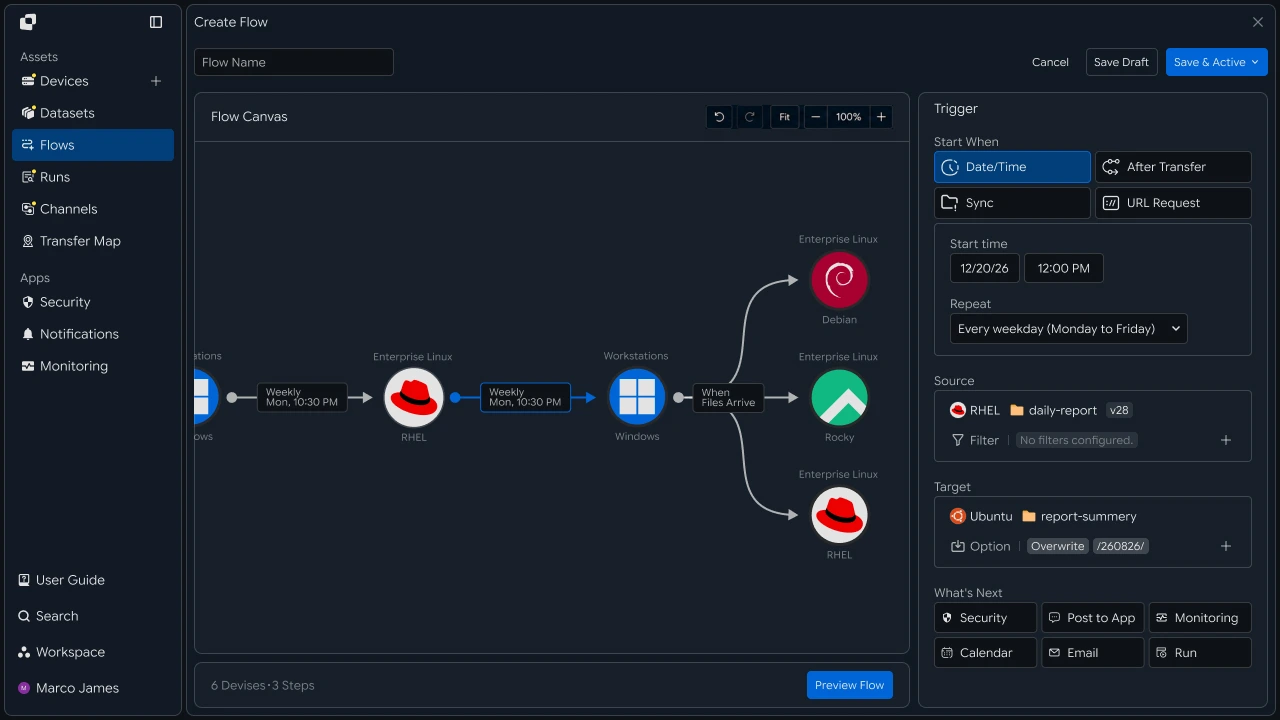
By linking job conditions, you can run the workflow in sequence from data collection through AI processing and model generation based on the processing status at each stage.
Result Transfer#
Send generated models and processing results to the systems that need them
Once training and processing are complete, send the generated model files and result data to the next environment.
Connect the locations where files will be used—such as model storage, inference systems, validation environments, and business systems—and send each output to the appropriate destination.
When a model or result file is used across multiple environments, you can connect destination-specific file flows and automatically extend the workflow to every required working location.
Run Management#
Track processing status stage by stage, from data to models and results
For each workflow run, you can view the overall flow together with the status of each stage.
You can track processed files and progress step by step across data collection, preprocessing, AI processing, model generation, and result transfer.
AI WorkflowData Collection✓Processing✓Model Training●Result Transfer○
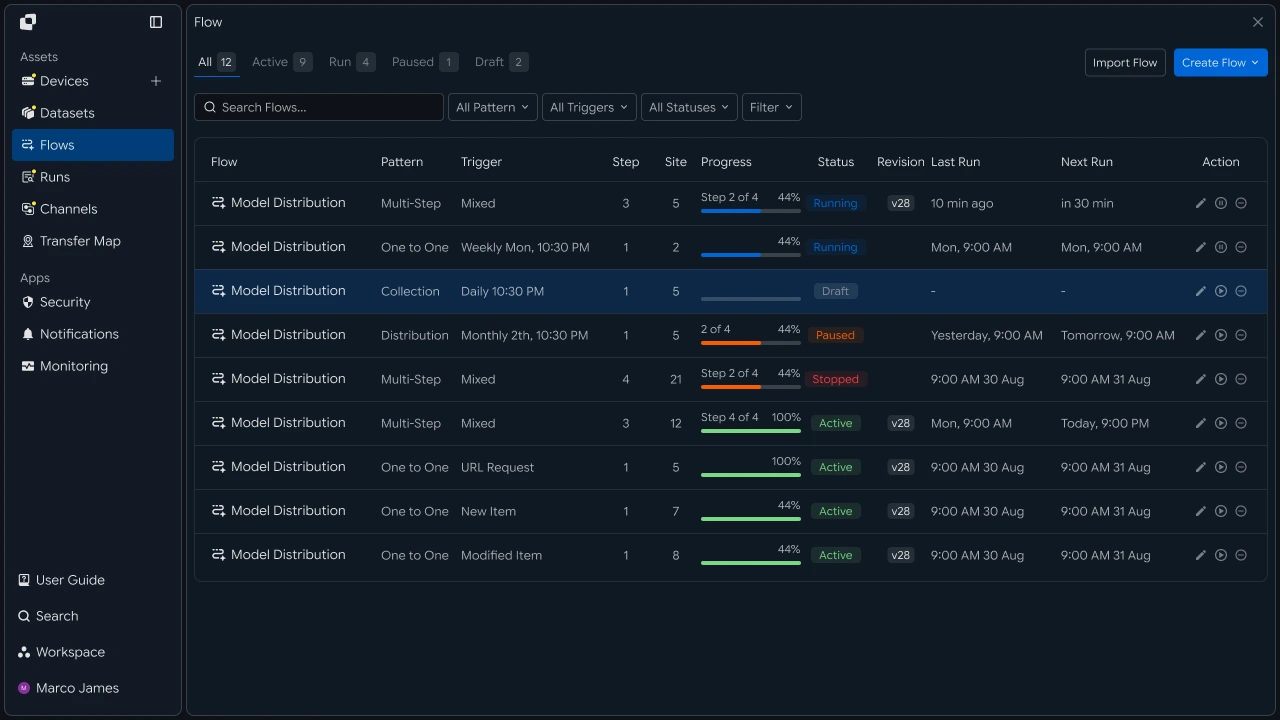
Key items to check include:
| Check Item | Details |
|---|---|
| Stage | The workflow stage currently running |
| Source | The system and file location from which data was collected |
| Files | Number of processed files and total size |
| Progress | Processing progress for each stage |
| Target | Destination for model and result files |
| Status | Execution result for the overall workflow and each task |
This lets you manage the status of a specific stage alongside the overall AI file workflow.
Exception Handling#
Check transfer and processing status, then rerun the stages that need attention
When a stage requires additional investigation during execution, review the data status, system connections, and file transfer results using the task details and execution history.
You can review each stage separately from data collection through AI processing and result transfer, then rerun the required task.

Developer#
Deploy datasets to multiple training nodes and collect node-specific results on a storage system
Integration Setup#
Prepare shared API call code and path conventions
import os
import requests

BASE_URL = os.getenv("INNORIX_BASE_URL", "https://app.innorix.com").rstrip("/")
TOKEN = os.environ["INNORIX_ACCESS_TOKEN"]
WORKSPACE_ID = os.getenv("INNORIX_WORKSPACE_ID")   # optional; falls back to the current workspace

STATUS_COMPLETE = 2
TERMINAL = {2, 4, 5, 9, 99}          # complete / error / cancelled / partial / failed
NOT_SUCCEEDED = {4, 5, 9, 99}


def api(method, path, body=None, params=None):
    headers = {
        "Content-Type": "application/json",
        "Authorization": f"Bearer {TOKEN}",
    }

    if WORKSPACE_ID:
        headers["x-workspace-id"] = WORKSPACE_ID

    response = requests.request(
        method, BASE_URL + path,
        headers=headers, json=body, params=params, timeout=30,
    )

    payload = response.json() if response.content else {}

    if not response.ok:
        raise RuntimeError(payload.get("message") or f"HTTP {response.status_code}")

    return payload.get("data")


def is_terminal(detail):
    return detail.get("isTerminal", detail.get("status") in TERMINAL)
// InnorixClient.java
public static final String BASE_URL =
env("INNORIX_BASE_URL", "https://app.innorix.com").replaceAll("/+quot;, "");
public static final String WORKSPACE_ID = env("INNORIX_WORKSPACE_ID", null);
public static final int STATUS_COMPLETE = 2;
// States the transfer no longer moves out of
public static final Set<Integer> TERMINAL = Set.of(2, 4, 5, 9, 99);
// Terminal states that are not a full success
public static final Set<Integer> NOT_SUCCEEDED = Set.of(4, 5, 9, 99);
private HttpRequest.Builder headers(HttpRequest.Builder builder) {
builder.header("Content-Type", "application/json")
.header("Authorization", "Bearer " + session.accessToken());
// When omitted the account's current workspace is used.
if (workspaceId != null) builder.header("x-workspace-id", workspaceId);
return builder;
}
/** Unwraps and returns data from the response. Throws ApiError on failure. */
public Object api(String method, String path, Object body, Map<String, Object> params) {
Resp response = request(method, path, body, params);
Object payload = null;
try {
payload = Json.parse(response.text());
} catch (RuntimeException ignored) {
payload = null;
}
if (!response.ok()) {
Map<String, Object> map = Json.asObj(payload);
String message = Json.str(map, "message", Json.str(map, "error", "unknown error"));
throw new ApiError(response.status, message, map);
}
return Json.get(payload, "data");
}
/** Use the server flag when present, otherwise fall back to the status code. */
public static boolean isTerminal(Map<String, Object> record) {
Boolean flag = Json.boolOrNull(record, "isTerminal");
if (flag != null) return flag;
Integer status = Json.intOrNull(record, "status");
return status != null && TERMINAL.contains(status);
}// innorix-client.js
const BASE_URL = (process.env.INNORIX_BASE_URL
|| "https://app.innorix.com").replace(/\/+$/, "");
const TOKEN = process.env.INNORIX_ACCESS_TOKEN;
const WORKSPACE_ID = process.env.INNORIX_WORKSPACE_ID || null;
export const STATUS_COMPLETE = 2;
export const TERMINAL = new Set([2, 4, 5, 9, 99]); // complete / error / cancelled / partial / failed
export const NOT_SUCCEEDED = new Set([4, 5, 9, 99]);
export async function api(method, path, body = null, params = null) {
const url = new URL(BASE_URL + path);
if (params) {
for (const [key, value] of Object.entries(params)) {
if (value === undefined || value === null) continue;
url.searchParams.set(key, String(value));
}
}
const headers = {
"Content-Type": "application/json",
Authorization: `Bearer ${TOKEN}`,
};
// When omitted the account's current workspace is used.
if (WORKSPACE_ID) headers["x-workspace-id"] = WORKSPACE_ID;
const response = await fetch(url, {
method,
headers,
body: body === null ? undefined : JSON.stringify(body),
signal: AbortSignal.timeout(30_000),
});
const payload = await response.json().catch(() => ({}));
if (!response.ok) {
throw new Error(payload.message || `HTTP ${response.status}`);
}
return payload.data;
}
export function isTerminal(detail) {
return detail.isTerminal !== undefined
? detail.isTerminal
: TERMINAL.has(detail.status);
}// InnorixClient.cs
public static readonly string BaseUrl =
Env("INNORIX_BASE_URL", "https://app.innorix.com").TrimEnd('/');
public static readonly string WorkspaceIdFromEnv = Env("INNORIX_WORKSPACE_ID", null);
public const int StatusComplete = 2;
/// <summary>States the transfer no longer moves out of</summary>
public static readonly HashSet<int> Terminal = new HashSet<int> { 2, 4, 5, 9, 99 };
/// <summary>Terminal states that are not a full success</summary>
public static readonly HashSet<int> NotSucceeded = new HashSet<int> { 4, 5, 9, 99 };
// Applied on every request
request.Headers.TryAddWithoutValidation("Authorization", "Bearer " + Session.AccessToken);
// When omitted the account's current workspace is used.
if (WorkspaceId != null) request.Headers.TryAddWithoutValidation("x-workspace-id", WorkspaceId);
public async Task<JsonNode> ApiAsync(string method, string path, JsonNode body = null,
IDictionary<string, object> parameters = null)
{
Resp response = await RequestAsync(method, path, body, parameters).ConfigureAwait(false);
JsonNode payload = null;
try
{
payload = J.Parse(response.Text());
}
catch (Exception)
{
payload = null;
}
if (!response.Ok)
{
JsonObject map = J.AsObj(payload);
string message = J.Str(map, "message", J.Str(map, "error", "unknown error"));
throw new ApiError(response.Status, message, map);
}
return J.Get(payload, "data");
}
/// <summary>Use the server flag when present, otherwise fall back to the status code.</summary>
public static bool IsTerminal(JsonObject record)
{
bool? flag = J.BoolOrNull(record, "isTerminal");
if (flag != null) return flag.Value;
int? status = J.IntOrNull(record, "status");
return status != null && Terminal.Contains(status.Value);
}import base64
import time
def encode_path(device_id, raw_path):
normalized = str(raw_path or "").replace("\\", "/")
token = base64.b64encode(normalized.encode("utf-8")).decode("ascii")
return f"{device_id}_ino_{token}"
def now_iso():
return time.strftime("%Y-%m-%dT%H:%M:%S.000Z", time.gmtime())public static String encodePath(String deviceId, String rawPath) {
String normalized = (rawPath == null ? "" : rawPath).replace("\\", "/");
return deviceId + "_ino_"
+ Base64.getEncoder().encodeToString(normalized.getBytes(StandardCharsets.UTF_8));
}
public static String nowIso() {
return Instant.now().truncatedTo(ChronoUnit.SECONDS).toString().replace("Z", ".000Z");
}export function encodePath(deviceId, rawPath) {
const normalized = String(rawPath ?? "").replace(/\\/g, "/");
const token = Buffer.from(normalized, "utf8").toString("base64");
return `${deviceId}_ino_${token}`;
}
export function nowIso() {
return new Date().toISOString().replace(/\.\d{3}Z$/, ".000Z");
}public static string EncodePath(string deviceId, string rawPath)
{
string normalized = (rawPath ?? "").Replace("\\", "/");
return deviceId + "_ino_" + Convert.ToBase64String(Encoding.UTF8.GetBytes(normalized));
}
public static string NowIso()
{
return DateTime.UtcNow.ToString("yyyy-MM-dd'T'HH:mm:ss'.000Z'",
System.Globalization.CultureInfo.InvariantCulture);
}Transfer status is determined using the values below. There are five terminal states, and the value representing success is Complete (2).
| Status Value | Meaning | Terminal |
|---|---|---|
| 2 | Complete | Yes |
| 4 | Error | Yes |
| 5 | Cancelled | Yes |
| 9 | Partially Complete | Yes |
| 99 | Failed | Yes |
| 1, 6, 12, 13 | Started, Transferring, Synchronizing, Receiving | No |
Path Rules#
Include the dataset version and run identifier in the path
As runs accumulate, it becomes difficult to tell which result came from which dataset. By standardizing path rules in functions, you can avoid assembling path strings throughout the code.
DATA_ROOT = "/data"
WORK_ROOT = "/work"
ARCHIVE_ROOT = "/archive"


# source dataset on the storage device
def dataset_path(dataset, version):
    return f"{DATA_ROOT}/datasets/{dataset}/{version}"


# path the training job reads on the node
def node_input_path(dataset, version, run_id):
    return f"{WORK_ROOT}/{run_id}/input/{dataset}/{version}"


# path the node writes its results to
def node_output_path(run_id):
    return f"{WORK_ROOT}/{run_id}/output"


# archive path where results are collected
def archive_path(run_id):
    return f"{ARCHIVE_ROOT}/runs/{run_id}"


run_id = f"r-{time.strftime('%Y%m%d-%H%M%S')}"
static final String DATA_ROOT = "/data";
static final String WORK_ROOT = "/work";
static final String ARCHIVE_ROOT = "/archive";
// source dataset on the storage device
String datasetPath(String dataset, String version) {
return DATA_ROOT + "/datasets/" + dataset + "/" + version;
}
// path the training job reads on the node
String nodeInputPath(String dataset, String version, String runId) {
return WORK_ROOT + "/" + runId + "/input/" + dataset + "/" + version;
}
// path the node writes its results to
String nodeOutputPath(String runId) {
return WORK_ROOT + "/" + runId + "/output";
}
// archive path where results are collected
String archivePath(String runId) {
return ARCHIVE_ROOT + "/runs/" + runId;
}
String runId = "r-" + DateTimeFormatter.ofPattern("yyyyMMdd-HHmmss")
.withZone(ZoneOffset.UTC).format(Instant.now());const DATA_ROOT = "/data";
const WORK_ROOT = "/work";
const ARCHIVE_ROOT = "/archive";
// source dataset on the storage device
const datasetPath = (dataset, version) => `${DATA_ROOT}/datasets/${dataset}/${version}`;
// path the training job reads on the node
const nodeInputPath = (dataset, version, runId) =>
`${WORK_ROOT}/${runId}/input/${dataset}/${version}`;
// path the node writes its results to
const nodeOutputPath = (runId) => `${WORK_ROOT}/${runId}/output`;
// archive path where results are collected
const archivePath = (runId) => `${ARCHIVE_ROOT}/runs/${runId}`;
const runId = `r-${new Date().toISOString().replace(/[-:T]/g, "").slice(0, 15)}`;const string DataRoot = "/data";
const string WorkRoot = "/work";
const string ArchiveRoot = "/archive";
// source dataset on the storage device
string DatasetPath(string dataset, string version) =>
quot;{DataRoot}/datasets/{dataset}/{version}";
// path the training job reads on the node
string NodeInputPath(string dataset, string version, string runId) =>
quot;{WorkRoot}/{runId}/input/{dataset}/{version}";
// path the node writes its results to
string NodeOutputPath(string runId) => quot;{WorkRoot}/{runId}/output";
// archive path where results are collected
string ArchivePath(string runId) => quot;{ArchiveRoot}/runs/{runId}";
string runId = quot;r-{DateTime.UtcNow:yyyyMMdd-HHmmss}";Putting the run identifier at the beginning of the path makes it easy to delete or move an entire run at once. Using only the date causes two runs on the same day to get mixed together, while using only the dataset name makes it difficult to distinguish results after a version change.
Data Deployment#
Send a dataset to multiple nodes and confirm that every node has received it
One transfer targets one destination. If there are multiple nodes, there are multiple transfers.
def deploy(storage, nodes, dataset, version, run_id):
    source_path = dataset_path(dataset, version)
    target_path = node_input_path(dataset, version, run_id)

    return {
        node: api("POST", "/api/transfers/manual", {
            "sourceDevice": storage,
            "targetDevice": node,
            "targetPath": target_path,
            "sourcePaths": [source_path],
            "sendAllFolder": True,
            "checkIntegrity": True,
            "transferOptions": {"target-action": "overwrite"},
        })["monitorId"]
        for node in nodes
}Map<String, String> deploy(String storage, List<String> nodes,
String dataset, String version, String runId) {
String sourcePath = datasetPath(dataset, version);
String targetPath = nodeInputPath(dataset, version, runId);
Map<String, String> transfers = new LinkedHashMap<>();
for (String node : nodes) {
Map<String, Object> transfer = client.apiObj("POST", "/api/transfers/manual", Json.newObj(
"sourceDevice", storage,
"targetDevice", node,
"targetPath", targetPath,
"sourcePaths", List.of(sourcePath),
"sendAllFolder", true,
"checkIntegrity", true,
"transferOptions", Json.newObj("target-action", "overwrite")));
transfers.put(node, Json.str(transfer, "monitorId"));
}
return transfers;
}async function deploy(storage, nodes, dataset, version, runId) {
const sourcePath = datasetPath(dataset, version);
const targetPath = nodeInputPath(dataset, version, runId);
const transfers = {};
for (const node of nodes) {
const transfer = await client.api("POST", "/api/transfers/manual", {
sourceDevice: storage,
targetDevice: node,
targetPath,
sourcePaths: [sourcePath],
sendAllFolder: true,
checkIntegrity: true,
transferOptions: { "target-action": "overwrite" },
});
transfers[node] = transfer.monitorId;
}
return transfers;
}async Task<Dictionary<string, string>> DeployAsync(string storage,
IEnumerable<string> nodes, string dataset, string version, string runId)
{
string sourcePath = DatasetPath(dataset, version);
string targetPath = NodeInputPath(dataset, version, runId);
var transfers = new Dictionary<string, string>();
foreach (string node in nodes)
{
JsonObject transfer = await client.ApiObjAsync("POST", "/api/transfers/manual",
new JsonObject
{
["sourceDevice"] = storage,
["targetDevice"] = node,
["targetPath"] = targetPath,
["sourcePaths"] = new JsonArray { sourcePath },
["sendAllFolder"] = true,
["checkIntegrity"] = true,
["transferOptions"] = new JsonObject { ["target-action"] = "overwrite" },
});
transfers[node] = J.Str(transfer, "monitorId");
}
return transfers;
}def wait(monitor_id, timeout=3600, interval=3):
deadline = time.time() + timeout
while time.time() < deadline:
detail = api("GET", f"/api/transfers/{monitor_id}")
if is_terminal(detail):
return detail
time.sleep(interval)
raise TimeoutError(monitor_id)
def failed_files(monitor_id):
result = api("GET", f"/api/transfers/{monitor_id}/files", params={
"state": "any", "size": 500,
}) or {}
return [r for r in (result.get("children") or [])
if r.get("status") in NOT_SUCCEEDED]
def retry_failed(monitor_id):
rows = failed_files(monitor_id)
if not rows:
return 0
api("POST", f"/api/transfers/{monitor_id}/retry", {
"filesRetry": [
{"filePath": r["sourceFilePath"], "isDir": bool(r.get("isFolder"))}
for r in rows
]
})
return len(rows)public Map<String, Object> wait(String monitorId, int timeoutSeconds, int intervalSeconds) {
long deadline = System.currentTimeMillis() + timeoutSeconds * 1000L;
while (System.currentTimeMillis() < deadline) {
Map<String, Object> detail = apiObj("GET", "/api/transfers/" + monitorId);
if (isTerminal(detail)) return detail;
sleep(intervalSeconds * 1000L);
}
throw new ApiError(0, "timeout waiting for " + monitorId);
}
public List<Map<String, Object>> failedFiles(String monitorId) {
List<Map<String, Object>> failed = new ArrayList<>();
for (Map<String, Object> row : transferFiles(monitorId)) {
Integer status = Json.intOrNull(row, "status");
if (status != null && NOT_SUCCEEDED.contains(status)) failed.add(row);
}
return failed;
}
public int retryFailed(String monitorId) {
List<Map<String, Object>> rows = failedFiles(monitorId);
if (rows.isEmpty()) return 0;
List<Object> filesRetry = new ArrayList<>();
for (Map<String, Object> row : rows) {
String path = Json.str(row, "sourceFilePath");
if (path == null) continue;
filesRetry.add(Json.newObj("filePath", path, "isDir", Json.bool(row, "isFolder", false)));
}
api("POST", "/api/transfers/" + monitorId + "/retry", Json.newObj("filesRetry", filesRetry));
return rows.size();
}const sleep = (ms) => new Promise((resolve) => setTimeout(resolve, ms));
export async function wait(monitorId, { timeout = 3600, interval = 3 } = {}) {
const deadline = Date.now() + timeout * 1000;
while (Date.now() < deadline) {
const detail = await api("GET", `/api/transfers/${monitorId}`);
if (isTerminal(detail)) return detail;
await sleep(interval * 1000);
}
throw new Error(`timeout waiting for ${monitorId}`);
}
export async function failedFiles(monitorId) {
const result = (await api("GET", `/api/transfers/${monitorId}/files`, null, {
state: "any", size: 500,
})) || {};
return (result.children || []).filter((row) => NOT_SUCCEEDED.has(row.status));
}
export async function retryFailed(monitorId) {
const rows = await failedFiles(monitorId);
if (rows.length === 0) return 0;
await api("POST", `/api/transfers/${monitorId}/retry`, {
filesRetry: rows
.filter((row) => row.sourceFilePath)
.map((row) => ({ filePath: row.sourceFilePath, isDir: Boolean(row.isFolder) })),
});
return rows.length;
}public async Task<JsonObject> WaitAsync(string monitorId, int timeoutSeconds = 3600,
int intervalSeconds = 3)
{
long deadline = Environment.TickCount64 + timeoutSeconds * 1000L;
while (Environment.TickCount64 < deadline)
{
JsonObject detail = await ApiObjAsync("GET", "/api/transfers/" + monitorId)
.ConfigureAwait(false);
if (IsTerminal(detail)) return detail;
await Task.Delay(intervalSeconds * 1000).ConfigureAwait(false);
}
throw new ApiError(0, "timeout waiting for " + monitorId);
}
public async Task<List<JsonObject>> FailedFilesAsync(string monitorId)
{
List<JsonObject> rows = await TransferFilesAsync(monitorId).ConfigureAwait(false);
return rows.Where(row =>
{
int? status = J.IntOrNull(row, "status");
return status != null && NotSucceeded.Contains(status.Value);
}).ToList();
}
/// <summary>Only callable once the transfer has reached a terminal state.</summary>
public async Task<int> RetryFailedAsync(string monitorId)
{
List<JsonObject> rows = await FailedFilesAsync(monitorId).ConfigureAwait(false);
if (rows.Count == 0) return 0;
var filesRetry = new JsonArray();
foreach (JsonObject row in rows)
{
string path = J.Str(row, "sourceFilePath");
if (path == null) continue;
filesRetry.Add(new JsonObject
{
["filePath"] = path,
["isDir"] = J.Bool(row, "isFolder", false),
});
}
await ApiAsync("POST", "/api/transfers/" + monitorId + "/retry",
new JsonObject { ["filesRetry"] = filesRetry }).ConfigureAwait(false);
return rows.Count;
}Do not start training if even one node has not received the data. Check every node instead of stopping at the first failure so you can determine the correct retry scope.
transfers = deploy(STORAGE, NODES, "imagenet", "v3", run_id)
results = {node: wait(mid) for node, mid in transfers.items()}

incomplete = [n for n, d in results.items() if d["status"] != STATUS_COMPLETE]

if incomplete:
raise RuntimeError(f"nodes not fully delivered: {', '.join(incomplete)}")Map<String, String> transfers = deploy(STORAGE, NODES, "imagenet", "v3", runId);
Map<String, Map<String, Object>> results = new LinkedHashMap<>();
for (var entry : transfers.entrySet()) {
results.put(entry.getKey(), client.await(entry.getValue(), 7200, null));
}
List<String> incomplete = new ArrayList<>();
results.forEach((node, detail) -> {
if (Json.intOr(detail, "status", -1) != InnorixClient.STATUS_COMPLETE) {
incomplete.add(node);
}
});
if (!incomplete.isEmpty()) {
throw new RuntimeException("Nodes not fully delivered: " + String.join(", ", incomplete));
}const transfers = await deploy(STORAGE, NODES, "imagenet", "v3", runId);
const results = {};
for (const [node, mid] of Object.entries(transfers)) {
results[node] = await wait(mid);
}
const incomplete = Object.entries(results)
.filter(([, d]) => d.status !== STATUS_COMPLETE)
.map(([node]) => node);
if (incomplete.length) {
throw new Error(`Nodes not fully delivered: ${incomplete.join(", ")}`);
}Dictionary<string, string> transfers = await DeployAsync(
STORAGE, NODES, "imagenet", "v3", runId);
var results = new Dictionary<string, JsonObject>();
foreach (var (node, mid) in transfers)
{
results[node] = await client.WaitAsync(mid, 7200);
}
var incomplete = results
.Where(kv => J.IntOrNull(kv.Value, "status") != InnorixClient.StatusComplete)
.Select(kv => kv.Key).ToList();
if (incomplete.Count > 0)
{
throw new Exception(quot;Nodes not fully delivered: {string.Join(", ", incomplete)}");
}Use overwrite as the arrival policy. With numbering, copies accumulate on the nodes, making it unclear which copy the training code should read.
Delta Transfer#
Send only the data that changed since the last deployment
monitor_id = api("POST", "/api/transfers/manual", {
    "sourceDevice": STORAGE,
    "targetDevice": node,
    "targetPath": node_input_path("imagenet", "v3", run_id),
    "sourcePaths": [dataset_path("imagenet", "v3")],
    "sendAllFolder": True,
    "incremental": True,
    "transferOptions": {"target-action": "overwrite"},
})["monitorId"]

detail = wait(monitor_id)
print(f"transferred {detail['fileCount']} files, {detail['totalSize']} bytes")Map<String, Object> transfer = client.apiObj("POST", "/api/transfers/manual", Json.newObj(
"sourceDevice", STORAGE,
"targetDevice", node,
"targetPath", nodeInputPath("imagenet", "v3", runId),
"sourcePaths", List.of(datasetPath("imagenet", "v3")),
"sendAllFolder", true,
"incremental", true,
"transferOptions", Json.newObj("target-action", "overwrite")));
String monitorId = Json.str(transfer, "monitorId");
Map<String, Object> detail = client.await(monitorId, 7200, null);
System.out.printf("Transferred %s files, %s bytes%n",
Json.str(detail, "fileCount"), Json.str(detail, "totalSize"));const transfer = await client.api("POST", "/api/transfers/manual", {
sourceDevice: STORAGE,
targetDevice: node,
targetPath: nodeInputPath("imagenet", "v3", runId),
sourcePaths: [datasetPath("imagenet", "v3")],
sendAllFolder: true,
incremental: true,
transferOptions: { "target-action": "overwrite" },
});
const monitorId = transfer.monitorId;
const detail = await wait(monitorId);
console.log(`Transferred ${detail.fileCount} files, ${detail.totalSize} bytes`);JsonObject transfer = await client.ApiObjAsync("POST", "/api/transfers/manual",
new JsonObject
{
["sourceDevice"] = STORAGE,
["targetDevice"] = node,
["targetPath"] = NodeInputPath("imagenet", "v3", runId),
["sourcePaths"] = new JsonArray { DatasetPath("imagenet", "v3") },
["sendAllFolder"] = true,
["incremental"] = true,
["transferOptions"] = new JsonObject { ["target-action"] = "overwrite" },
});
string monitorId = J.Str(transfer, "monitorId");
JsonObject detail = await client.WaitAsync(monitorId, 7200);
Console.WriteLine(quot;Transferred {J.Str(detail, "fileCount")} files, "
+ quot;{J.Str(detail, "totalSize")} bytes");It is disabled by default. The node's agent calculates the changes and transfers only files that were added or modified since the last deployment.
Always use overwrite for incremental transfers. With numbering, changed files accumulate with numbered copies, and the training code may continue reading the old files.
Integrity Verification#
Verify that the transferred data matches the original
Integrity verification has two steps. Start verification with POST /api/transfers/{monitorId}/verification, then poll the result with GET while the server processes it.
def verify(monitor_id, timeout=1800, interval=10):
    api("POST", f"/api/transfers/{monitor_id}/verification", {})

    deadline = time.time() + timeout

    while time.time() < deadline:
        result = api("GET", f"/api/transfers/{monitor_id}/verification") or {}

        if result.get("verified"):
            return result

        time.sleep(interval)

    raise TimeoutError(f"verification: {monitor_id}")


result = verify(monitor_id)

if result["sourceFileCount"] != result["targetFileCount"]:
    raise RuntimeError("file counts differ - part of the transfer is missing")

if not result["checksumMatched"]:
    for row in result.get("mismatchedFiles") or []:
print("mismatch:", row)Map<String, Object> result = client.verify(monitorId, 1800, 10);
if (!Json.str(result, "sourceFileCount").equals(Json.str(result, "targetFileCount"))) {
throw new RuntimeException("File counts differ. Part of the transfer is missing.");
}
if (!Json.bool(result, "checksumMatched", false)) {
for (Object row : Json.arrOf(result, "mismatchedFiles")) {
System.out.println("Mismatch: " + row);
}
}const result = await verify(monitorId);
if (result.sourceFileCount !== result.targetFileCount) {
throw new Error("File counts differ. Part of the transfer is missing.");
}
if (!result.checksumMatched) {
for (const row of result.mismatchedFiles || []) {
console.log("Mismatch:", row);
}
}JsonObject result = await client.VerifyAsync(monitorId);
if (J.Str(result, "sourceFileCount") != J.Str(result, "targetFileCount"))
{
throw new Exception("File counts differ. Part of the transfer is missing.");
}
if (!J.Bool(result, "checksumMatched", false))
{
foreach (JsonNode row in J.ArrOf(result, "mismatchedFiles"))
{
Console.WriteLine(quot;Mismatch: {row}");
}
}| Response Item | Description |
|---|---|
checksumAlgorithm |
Checksum algorithm used |
sourceFileCount, targetFileCount |
Number of files at the source and target |
checksumMatched |
Whether the checksums match |
mismatchedCount, mismatchedFiles |
Number and list of mismatched files |
If the file counts differ, the transfer is incomplete. If the counts match but there are mismatches, the contents were corrupted. The former can be resolved by retransmission; the latter requires finding the cause.
Result Collection#
Collect node-specific outputs on a storage system without collisions
Every node uses the same filename, such as model.pt. If everything is collected into one path, the files will overwrite one another.
def collect(nodes, archive, run_id):
    transfers = {}

    for node in nodes:
        target_path = f"{archive_path(run_id)}/{node}"

        transfers[node] = api("POST", "/api/transfers/manual", {
            "sourceDevice": node,
            "targetDevice": archive,
            "targetPath": target_path,
            "sourcePaths": [node_output_path(run_id)],
            "sendAllFolder": True,
            "checkIntegrity": True,
            "transferOptions": {"target-action": "overwrite"},
        })["monitorId"]

return transfersMap<String, String> collect(List<String> nodes, String archive, String runId) {
Map<String, String> transfers = new LinkedHashMap<>();
for (String node : nodes) {
String targetPath = archivePath(runId) + "/" + node;
Map<String, Object> transfer = client.apiObj("POST", "/api/transfers/manual", Json.newObj(
"sourceDevice", node,
"targetDevice", archive,
"targetPath", targetPath,
"sourcePaths", List.of(nodeOutputPath(runId)),
"sendAllFolder", true,
"checkIntegrity", true,
"transferOptions", Json.newObj("target-action", "overwrite")));
transfers.put(node, Json.str(transfer, "monitorId"));
}
return transfers;
}async function collect(nodes, archive, runId) {
const transfers = {};
for (const node of nodes) {
const targetPath = `${archivePath(runId)}/${node}`;
const transfer = await client.api("POST", "/api/transfers/manual", {
sourceDevice: node,
targetDevice: archive,
targetPath,
sourcePaths: [nodeOutputPath(runId)],
sendAllFolder: true,
checkIntegrity: true,
transferOptions: { "target-action": "overwrite" },
});
transfers[node] = transfer.monitorId;
}
return transfers;
}async Task<Dictionary<string, string>> CollectAsync(
IEnumerable<string> nodes, string archive, string runId)
{
var transfers = new Dictionary<string, string>();
foreach (string node in nodes)
{
string targetPath = quot;{ArchivePath(runId)}/{node}";
JsonObject transfer = await client.ApiObjAsync("POST", "/api/transfers/manual",
new JsonObject
{
["sourceDevice"] = node,
["targetDevice"] = archive,
["targetPath"] = targetPath,
["sourcePaths"] = new JsonArray { NodeOutputPath(runId) },
["sendAllFolder"] = true,
["checkIntegrity"] = true,
["transferOptions"] = new JsonObject { ["target-action"] = "overwrite" },
});
transfers[node] = J.Str(transfer, "monitorId");
}
return transfers;
}/archive/runs/r-20260901-0200/dev-gpu-01/model.ptPTmetrics.jsonJSONdev-gpu-02/model.ptPTmetrics.jsonJSON
Including the node identifier in the destination path is the simplest approach. If you avoid collisions with numbering, you cannot tell which node model_1.pt came from.
Collect metrics and logs along with the model files. The cause of a failed training run is recorded in the logs, but those logs will be deleted when the node is reclaimed.
Connect Deployment and Collection#
Automatically start collection when deployment finishes
The code above waits for the client to finish before calling the next step. If training takes several hours, the process must stay alive the entire time, and collection will not happen if it dies.
import uuid

flow_id = str(uuid.uuid4())


def build_step(name, source, source_path, target, target_path,
               step, trigger_id=None, webhook=None):
    schedule = {
        "type": "none",
        "startDateType": "now",
        "startDate": now_iso(),
        "timezone": "Asia/Seoul",
    }

    if trigger_id:
        schedule["triggerAutomation"] = {"value": trigger_id}

    body = {
        "name": name,
        "flowName": name,
        "flowId": flow_id,
        "transferType": "normal",
        "timezone": "Asia/Seoul",
        "step": step,
        "isUpcoming": False,
        "details": [
            {
                "senderId": source,
                "receiverId": target,
                "sourceItem": [
                    {
                        "hash": encode_path(source, source_path),
                        "filePath": source_path,
                        "isDir": True,
                    }
                ],
                "targetPath": encode_path(target, target_path),
                "step": step,
                "transferOptions": {
                    "noSchedule": False,
                    "target-action": "overwrite",
                    "send-fileoption": {},
                },
            }
        ],
        "schedules": [schedule],
    }

    if webhook:
        body["processors"] = [{
            "category": "run",
            "type": "http",
            "config": {"url": webhook, "method": "POST"},
        }]

    return body


deploy_id = api("POST", "/api/automations", build_step(
    f"deploy imagenet:v3", STORAGE, dataset_path("imagenet", "v3"),
    node, node_input_path("imagenet", "v3", run_id),
    step=1, webhook=TRAIN_HOOK))["automationId"]

collect_id = api("POST", "/api/automations", build_step(
    f"collect {run_id}", node, node_output_path(run_id),
    ARCHIVE, f"{archive_path(run_id)}/{node}",
    step=2, trigger_id=deploy_id))["automationId"]
String flowId = UUID.randomUUID().toString();
Map<String, Object> buildStep(String name, String source, String sourcePath,
String target, String targetPath, int step,
String triggerId, String webhook) {
Map<String, Object> schedule = new LinkedHashMap<>(Json.newObj(
"type", "none", "startDateType", "now",
"startDate", InnorixClient.nowIso(), "timezone", "Asia/Seoul"));
if (triggerId != null) {
schedule.put("triggerAutomation", Json.newObj("value", triggerId));
}
Map<String, Object> detail = Json.newObj(
"senderId", source, "receiverId", target,
"sourceItem", List.of(Json.newObj(
"hash", InnorixClient.encodePath(source, sourcePath),
"filePath", sourcePath, "isDir", true)),
"targetPath", InnorixClient.encodePath(target, targetPath),
"step", step,
"transferOptions", Json.newObj(
"noSchedule", false, "target-action", "overwrite",
"send-fileoption", Json.newObj()));
Map<String, Object> body = new LinkedHashMap<>(Json.newObj(
"name", name, "flowName", name, "flowId", flowId,
"transferType", "normal", "timezone", "Asia/Seoul",
"step", step, "isUpcoming", false,
"details", List.of(detail),
"schedules", List.of(schedule)));
if (webhook != null) {
body.put("processors", List.of(Json.newObj(
"category", "run", "type", "http",
"config", Json.newObj("url", webhook, "method", "POST"))));
}
return body;
}import { randomUUID } from "node:crypto";
const flowId = randomUUID();
function buildStep(name, source, sourcePath, target, targetPath, {
step, triggerId = null, webhook = null,
}) {
const schedule = {
type: "none", startDateType: "now",
startDate: nowIso(), timezone: "Asia/Seoul",
};
if (triggerId) schedule.triggerAutomation = { value: triggerId };
const body = {
name, flowName: name, flowId,
transferType: "normal", timezone: "Asia/Seoul",
step, isUpcoming: false,
details: [{
senderId: source, receiverId: target,
sourceItem: [{
hash: encodePath(source, sourcePath),
filePath: sourcePath, isDir: true,
}],
targetPath: encodePath(target, targetPath),
step,
transferOptions: {
noSchedule: false, "target-action": "overwrite",
"send-fileoption": {},
},
}],
schedules: [schedule],
};
if (webhook) {
body.processors = [{
category: "run", type: "http",
config: { url: webhook, method: "POST" },
}];
}
return body;
}string flowId = Guid.NewGuid().ToString();
JsonObject BuildStep(string name, string source, string sourcePath,
string target, string targetPath, int step,
string triggerId = null, string webhook = null)
{
var schedule = new JsonObject
{
["type"] = "none", ["startDateType"] = "now",
["startDate"] = InnorixClient.NowIso(), ["timezone"] = "Asia/Seoul",
};
if (triggerId != null)
schedule["triggerAutomation"] = new JsonObject { ["value"] = triggerId };
var detail = new JsonObject
{
["senderId"] = source, ["receiverId"] = target,
["sourceItem"] = new JsonArray
{
new JsonObject
{
["hash"] = InnorixClient.EncodePath(source, sourcePath),
["filePath"] = sourcePath, ["isDir"] = true,
},
},
["targetPath"] = InnorixClient.EncodePath(target, targetPath),
["step"] = step,
["transferOptions"] = new JsonObject
{
["noSchedule"] = false, ["target-action"] = "overwrite",
["send-fileoption"] = new JsonObject(),
},
};
var body = new JsonObject
{
["name"] = name, ["flowName"] = name, ["flowId"] = flowId,
["transferType"] = "normal", ["timezone"] = "Asia/Seoul",
["step"] = step, ["isUpcoming"] = false,
["details"] = new JsonArray { detail },
["schedules"] = new JsonArray { schedule },
};
if (webhook != null)
{
body["processors"] = new JsonArray
{
new JsonObject
{
["category"] = "run", ["type"] = "http",
["config"] = new JsonObject { ["url"] = webhook, ["method"] = "POST" },
},
};
}
return body;
}There are four items that must be handled correctly in the automation request.
| Item | How to Specify It |
|---|---|
isUpcoming |
Must be false. The server default true ignores the schedule in the request and replaces it with a five-minute one-time schedule. For a step with triggerAutomation, the server forces this to false, so it only needs to be specified explicitly on the first step without a trigger. |
step |
Include it at both the top level and in details. It identifies the hop position within the flow. |
sourceItem |
Include both hash (path token) and filePath (plain-text path). |
syncType |
Include it inside transferOptions. 1 is one-way and 2 is bidirectional. |
All four items can be omitted and registration will still succeed, but runtime behavior will differ. If a recurring schedule runs only once and then stops, check isUpcoming first.
Once the two requests have been sent, the application's work is done. Save each step's identifier with the execution record so you can check its status later.
Training Invocation and Retry#
Start training when the data arrives and retransmit only failed files
The invocation occurs after the transfer completes, and the endpoint that receives the request handles it as follows.
def on_train_hook(payload):
    monitor_id = payload.get("monitorId")

    if monitor_id:
        detail = wait(monitor_id)

        if detail["status"] != STATUS_COMPLETE:
            return abort_run(payload)

    start_training(payload)
void onTrainHook(Map<String, Object> payload) throws Exception {
String monitorId = Json.str(payload, "monitorId");
if (monitorId != null) {
Map<String, Object> detail = client.await(monitorId, 7200, null);
if (Json.intOr(detail, "status", -1) != InnorixClient.STATUS_COMPLETE) {
abortRun(payload);
return;
}
}
startTraining(payload);
}async function onTrainHook(payload) {
const monitorId = payload.monitorId;
if (monitorId) {
const detail = await wait(monitorId);
if (detail.status !== STATUS_COMPLETE) return abortRun(payload);
}
return startTraining(payload);
}async Task OnTrainHookAsync(JsonObject payload)
{
string monitorId = J.Str(payload, "monitorId");
if (monitorId != null)
{
JsonObject detail = await client.WaitAsync(monitorId, 7200);
if (J.Int(detail, "status", -1) != InnorixClient.StatusComplete)
{
await AbortRunAsync(payload);
return;
}
}
await StartTrainingAsync(payload);
}Check results for each run in the execution history.
runs = api("GET", f"/api/automations/{deploy_id}/executions") or []
latest = runs[0] if runs else None

if latest and latest["status"] != STATUS_COMPLETE:
    print("deploy failed:", latest["monitorId"],
"retried", retry_failed(latest["monitorId"]), "files")List<Map<String, Object>> runs = client.executions(deployId);
Map<String, Object> latest = runs.isEmpty() ? null : runs.get(0);
if (latest != null
&& Json.intOr(latest, "status", -1) != InnorixClient.STATUS_COMPLETE) {
int count = client.retryFailed(Json.str(latest, "monitorId"));
System.out.println("Deployment failed: " + Json.str(latest, "monitorId")
+ " retried " + count + " files");
}const runs = (await client.executions(deployId)) || [];
const latest = runs[0] || null;
if (latest && latest.status !== STATUS_COMPLETE) {
const count = await client.retryFailed(latest.monitorId);
console.log("Deployment failed:", latest.monitorId, "retried", count, "files");
}List<JsonObject> runs = J.AsList(await client.ExecutionsAsync(deployId));
JsonObject latest = runs.Count > 0 ? runs[0] : null;
if (latest != null
&& J.IntOrNull(latest, "status") != InnorixClient.StatusComplete)
{
int count = await client.RetryFailedAsync(J.Str(latest, "monitorId"));
Console.WriteLine(quot;Deployment failed: {J.Str(latest, "monitorId")} retried {count} files");
}When the dataset is large, retransmitting everything because of a few failed files is a major waste.
| Check Item | Details |
|---|---|
| Path | Dataset version and run identifier |
| Deployment | Whether delivery to each node is complete |
| Verification | Whether file counts and checksums match |
| Collection | Destination path for each node's results |
| Flow | Run and status at each stage |
| Retransmission | Failed files and processing results |