
Getting Started#
Basic Concept#
Move files between two clouds without going through a local PC
S3 and Azure Blob store files and objects in different cloud environments.
When moving files between the two environments using an intermediate PC, the following process may be required.
For a one-time task with only a few files, you can download and process them directly. However, when repeatedly moving regularly generated data or large files, you must continuously manage the intermediate storage location.
By configuring a direct transfer, you can connect the Source and Target so files move directly between cloud environments.
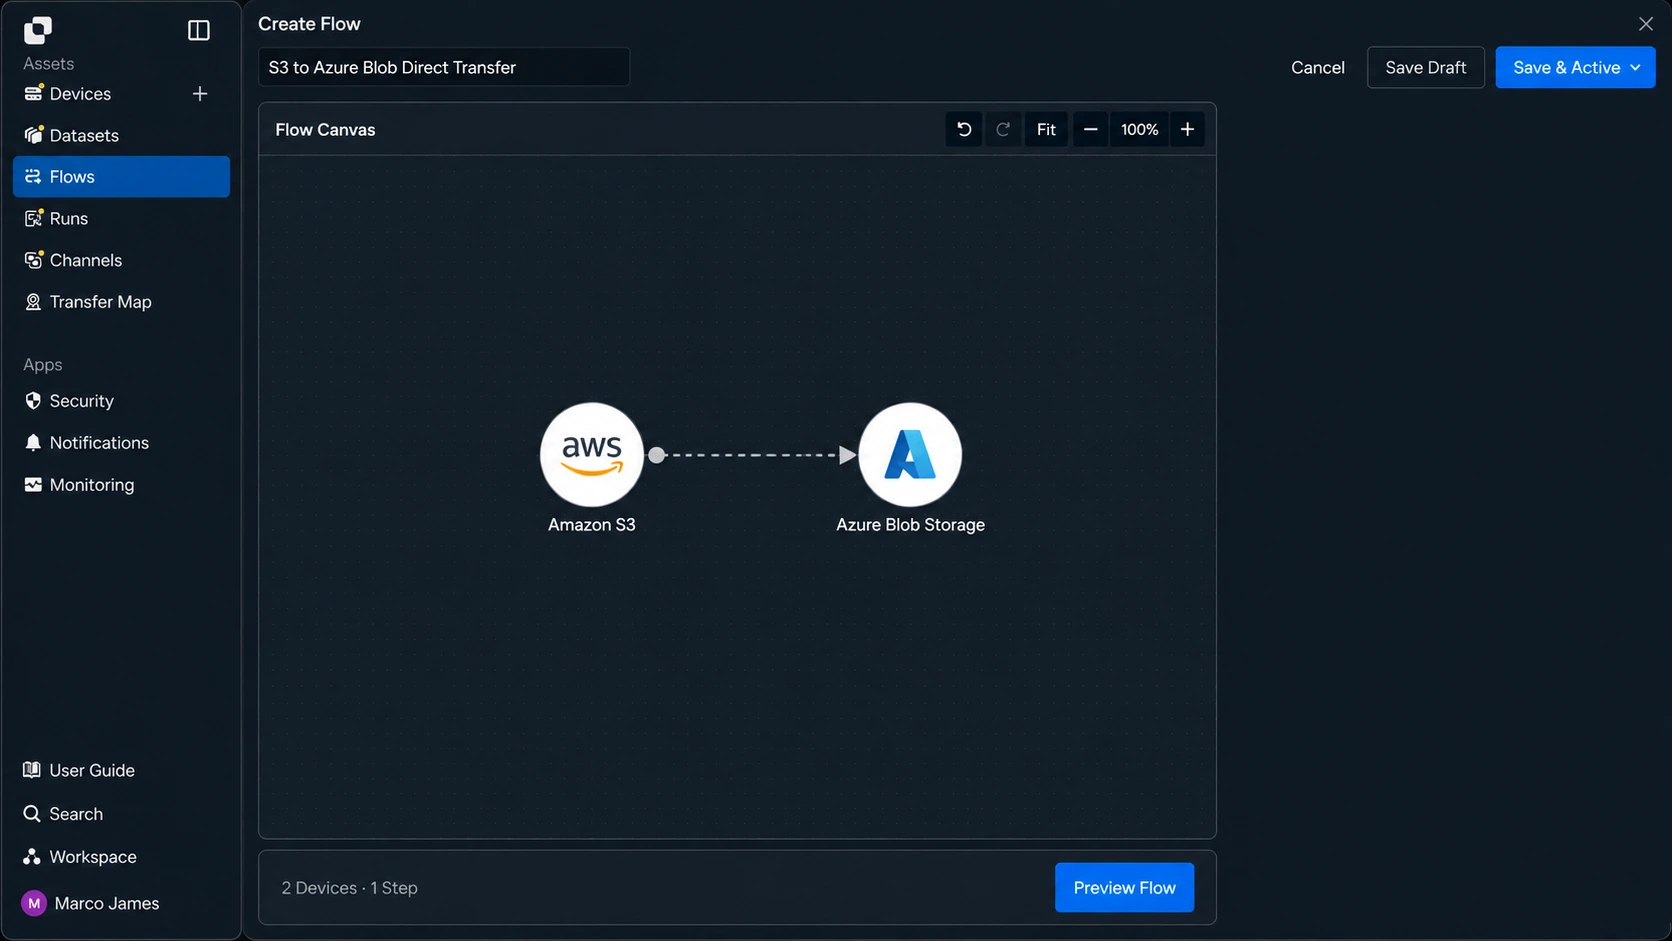
This reduces the intermediate steps of file download → local storage → re-upload, allowing files in S3 to be transferred directly to a specified location in Azure Blob.
Storage Location#
Connect the source path in S3 to the target Container in Azure Blob
For cloud-to-cloud transfers, instead of moving the entire Storage, you can configure the transfer scope by selecting only the paths required for actual work.
For example, if source data, logs, and backup files are stored together in an S3 bucket, you can transfer only the data path required by the analytics environment to Azure Blob.
source-bucketAmazon S3export/daily/Selectedmonthly/temporary/logs/backup/
Selected files are stored in the specified Container and path in Azure Blob.
analytics-containerAzure Blobincoming/daily/report-01.csvCSVreport-02.csvCSVreport-03.csvCSVarchive/
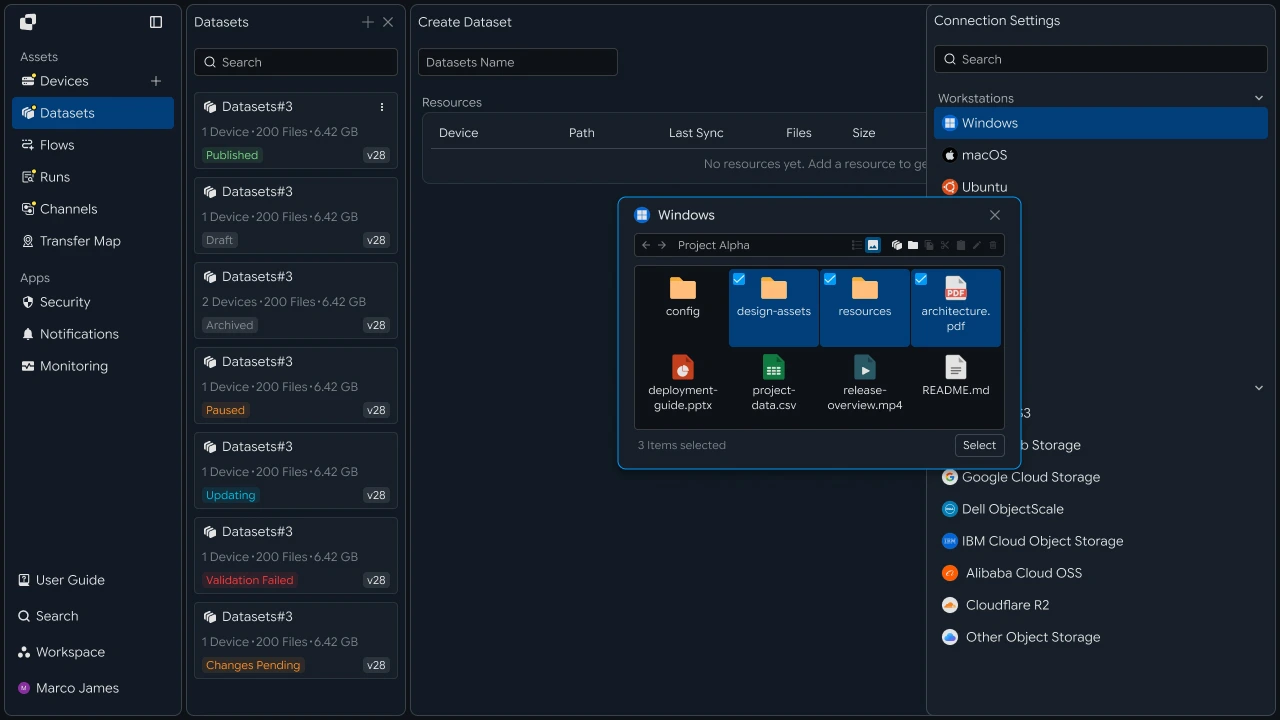
Transfer paths can be configured as follows depending on the task.
| Category | Source | Target |
|---|---|---|
| Storage | Amazon S3 | Azure Blob Storage |
| Storage Location | S3 Bucket / Prefix | Container / Blob Path |
| File Scope | Specified files or paths | Specified Container path |
| File Selection | Name, extension, path conditions | Store according to transfer results |
| Usage Environment | Source, collected data | Analytics, processing, archive environment |
This allows you to clearly separate and manage which files from which S3 paths are sent to which locations in Azure Blob, even when using different cloud services.
Execution Method#
Transfer once or run automatically for new and changed files
Moving files from S3 to Azure Blob does not need to be configured only as a one-time bulk migration.
Initially, you can transfer existing files to Azure Blob, then continuously apply only newly created or changed files.
For example, you can use the following methods.
| Transfer Purpose | Execution Method |
|---|---|
| Existing Data Migration | Transfer specified files at once |
| Daily Data Delivery | Run repeatedly at a scheduled time |
| Apply New Files | Run based on files created in the Source |
| Apply Changed Files | Check and transfer only changed files |
| Connect Follow-up Processing | Run the next transfer after the previous task completes |
You can select execution conditions based on how files are created in S3 and when they are used in the Azure environment.
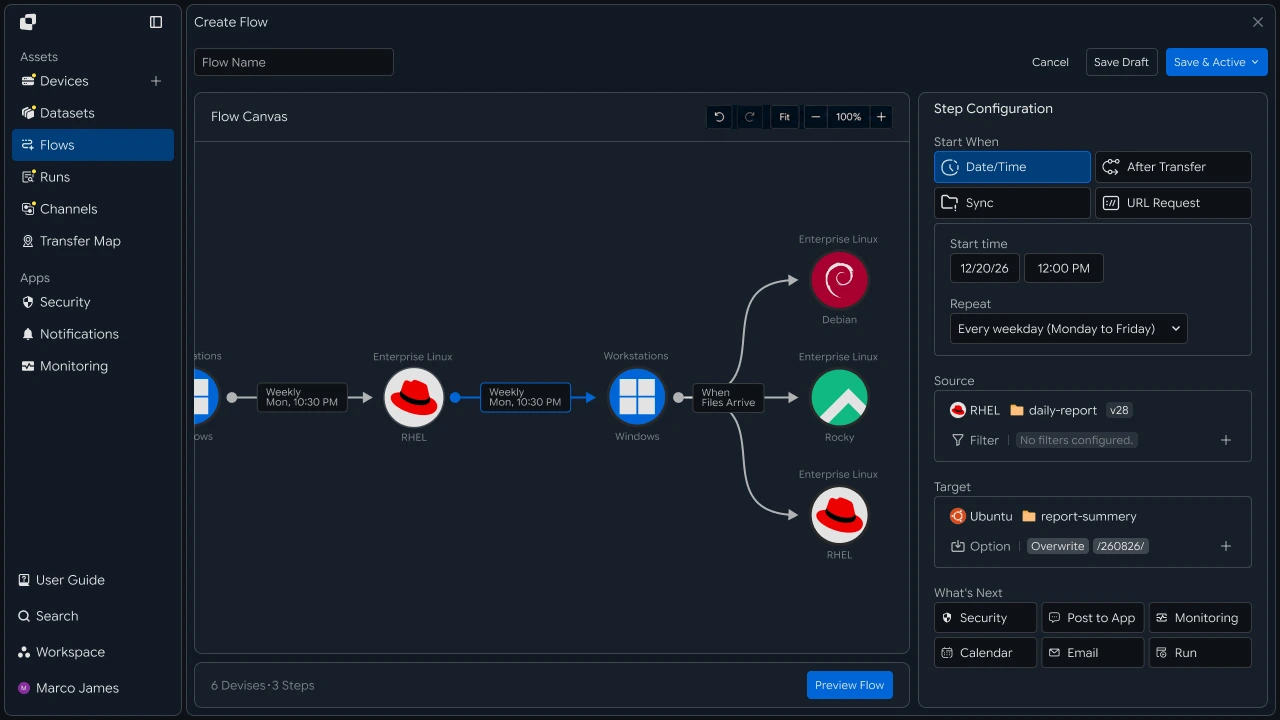
For example, if data files generated daily in S3 are used in an Azure analytics environment, you can configure the flow as follows.
- File Created in S3
- Check Transfer Conditions
- Select Target Files
- Transfer to Azure Blob
- Check Storage Results
Alternatively, you can first move a large volume of existing data and then continuously apply only changed files.
IT Engineer#
Cloud Connection#
Register Amazon S3 and Azure Blob separately in the transfer environment
First, connect Amazon S3, where files will be retrieved, and Azure Blob Storage, where files will be stored.
Because the two clouds are different services, manage the required access information separately for the Source and Target.
S3 must be able to read the bucket and files to transfer, while Azure Blob must be able to save files to the specified Container and path.
Cloud ConnectionsAmazon S3Source BucketRead FilesAzure Blob StorageTarget ContainerWrite Files
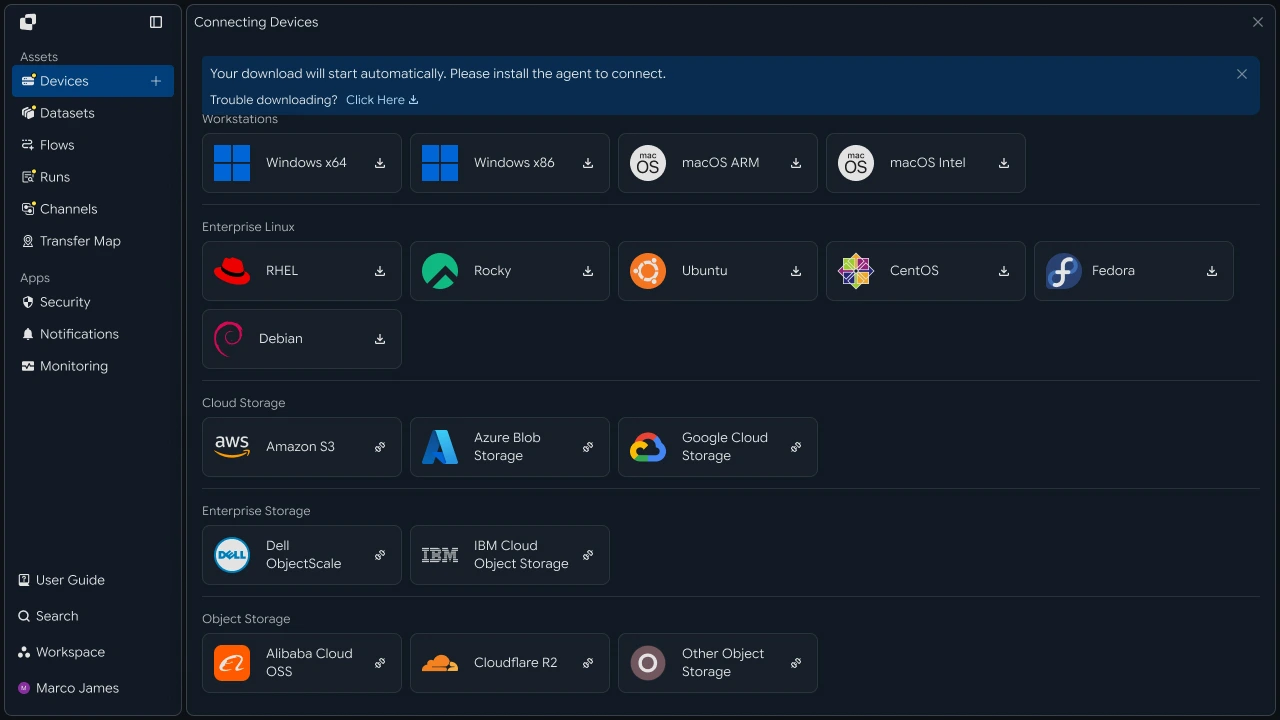
Before configuring the transfer, check the following items.
| Connection Environment | Check |
|---|---|
| Amazon S3 | Whether the Source Bucket is accessible |
| Source Permission | Read target files and paths |
| Azure Blob | Storage Account connection status |
| Target Container | Check file storage location |
| Target Permission | Whether Blobs can be created and stored |
| Transfer Path | Connection status between Source and Target locations |
Managing each cloud connection independently allows you to separate the access scope of the S3 and Azure environments while using both Storage services together in one Flow.
Transfer Path#
Directly connect the S3 Source and Azure Blob Target in one Flow
After preparing the connection environments, specify the S3 bucket and file path in the Source, and configure the Azure Blob Container and storage location in the Target.
For example, you can configure the following transfer path.
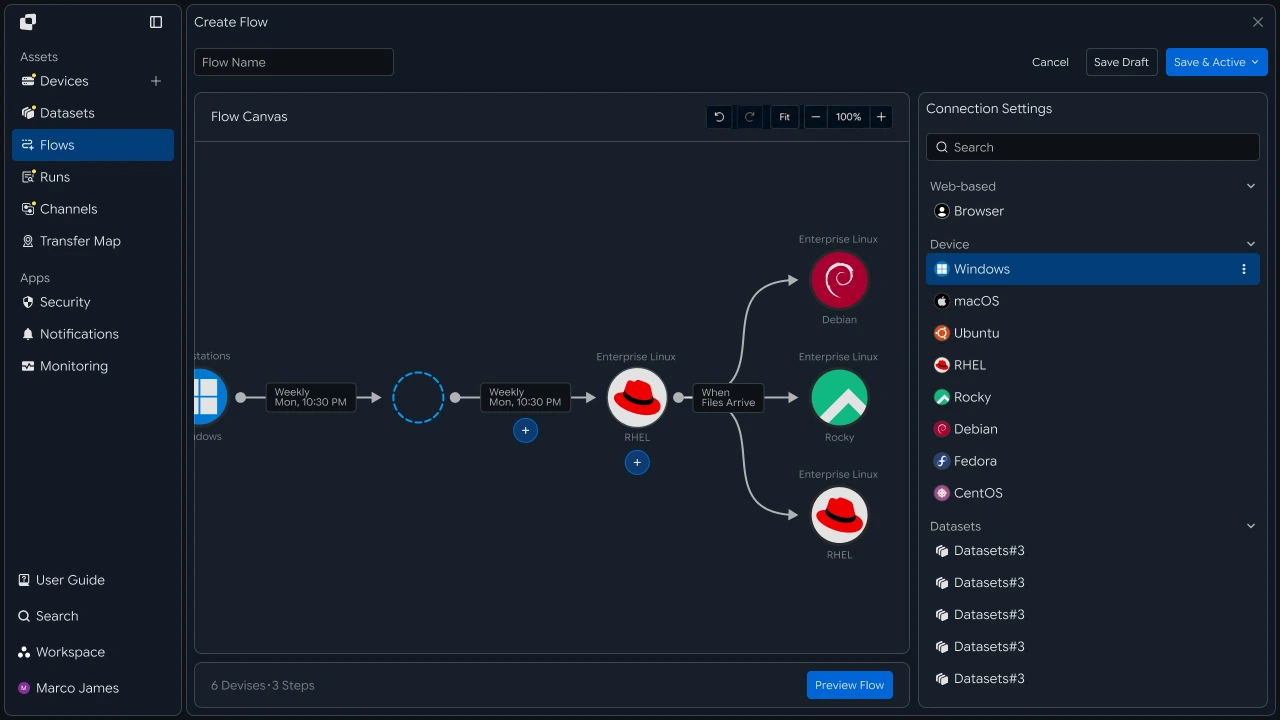
If necessary, you can branch one S3 path to multiple Azure Containers, or collect files from multiple S3 Sources into one Azure Blob Storage.
For example, Targets can be separated by data type as follows.
Amazon S3
- Azure Blobanalytics/
- Azure Blobarchive/
- Azure Blobprocessing/
In this way, you can start with a simple cloud-to-cloud transfer and later expand to multiple Azure storage locations based on file type or business purpose.
File Criteria#
Select only the required files and transfer them according to the target environment
Because S3 can store files used for multiple tasks together, you do not need to transfer every file to Azure Blob.
In a transfer task, you can select the files to actually transfer based on file name, extension, or path conditions along with the Source path.
For example, you can configure the following.
| File Condition | Transfer Processing |
|---|---|
*.csv |
Transfer to Azure analytics Container |
*.json |
Transfer to data processing path |
*.zip |
Transfer to compressed file archive path |
temporary/* |
Exclude from transfer |
| Changed Files | Retransfer only changed files |
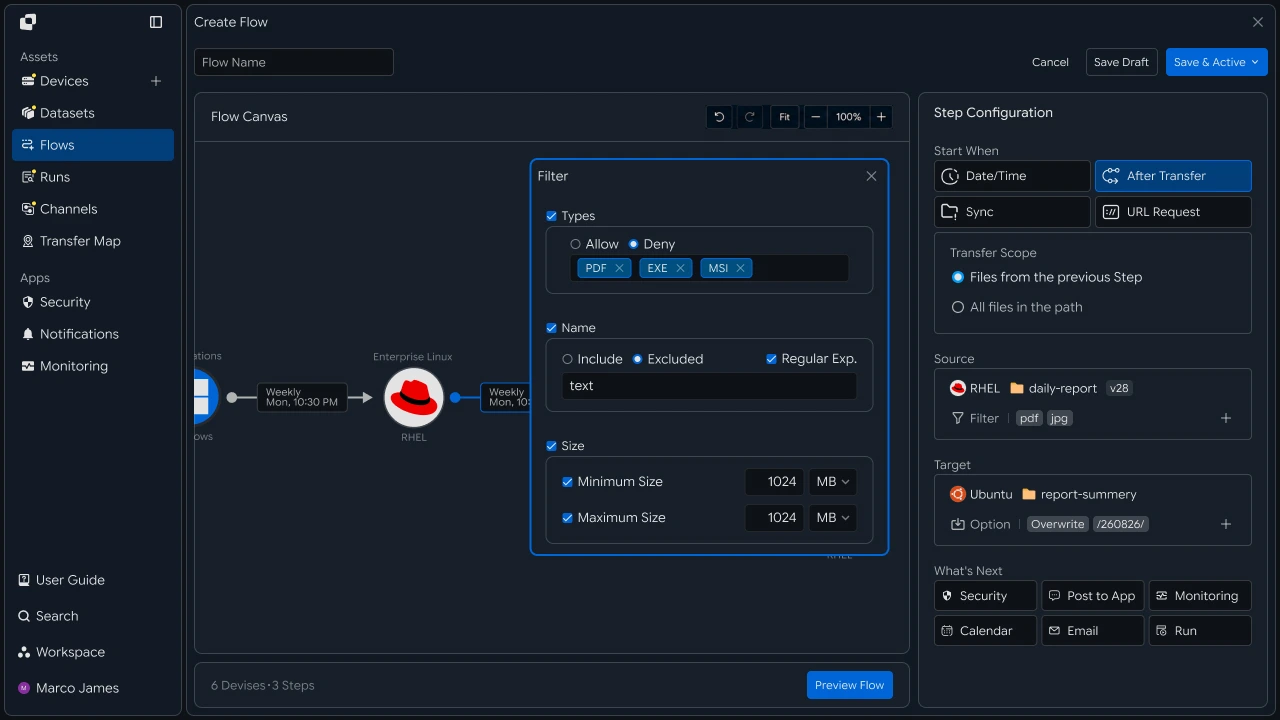
This allows you to configure a flow that selectively transfers only the data actually required in the Azure environment instead of repeatedly moving all S3 data.
Processing Connection#
Continue to the next task in the Azure environment after file transfer
After S3 files are stored in Azure Blob, you can automatically connect the next task that uses those files.
For example, after files are successfully applied to Azure Blob, you can run a data processing task or configure the processed results to be moved to another storage location.
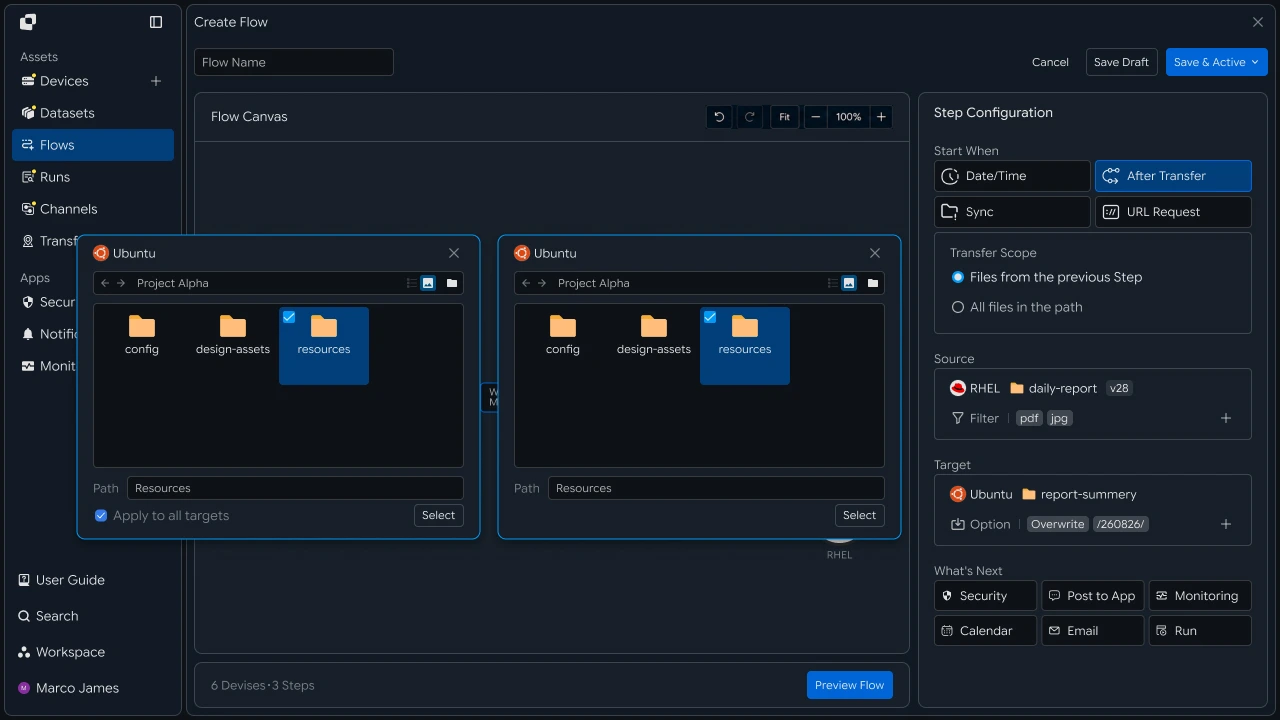
Follow-up tasks can be configured separately from the transfer itself, allowing the next task to run only when the file arrives successfully.
| Connection Target | Usage |
|---|---|
| Data Processing | Use files stored in Blob in the next processing environment |
| Next Flow | Deliver files to another Storage or system |
| Business Notification | Send transfer completion or failure results |
| Operations Check | Check execution status and file processing results |
This goes beyond simply moving files from S3 to Azure Blob and allows you to connect the actual tasks required in the Azure environment after file transfer into a single flow.
Result Verification#
Check transferred files and the applied results in Azure Blob together
When a transfer task runs, you can check the overall progress and transfer results in Runs.
When you select a specific Run, you can check the Source and Target, the number of processed files, and the total transfer volume, and if necessary, review processing results for each file.

The following items can be checked in the transfer results.
| Item | Details |
|---|---|
| Source | Amazon S3 bucket and source path |
| Target | Azure Blob Container and storage location |
| Total Files | Total number of files to transfer |
| Total Size | Total transfer size |
| Progress | File transfer progress |
| Status | Completed, In Progress, Failed status |
| Started | Transfer start time |
| Completed | Final completion time |
For example, after a Run completes, instead of checking only the Completed status, you can also verify that the specified number of files and storage results were correctly applied to the actual Target.
Exception Handling#
Separate the Source and Target environments to identify issues and rerun
If an issue occurs during a direct transfer from S3 to Azure Blob, first determine whether additional checks are required in the Source or Target environment.
For example, if Source files cannot be read, check the S3 connection and file access scope. If files cannot be saved to the Target, check the Azure Blob Container and storage permissions.

After rerunning, you can use the new Run to verify that the files were successfully stored in the specified Azure Blob location.
Applying this recipe lets you configure a single flow covering Connect Amazon S3 → Select Transfer Files and Paths → Configure Azure Blob Target → Set Execution Conditions → Direct Cloud-to-Cloud Transfer → Connect Follow-up Tasks → Check Run Results → Verify Target Storage Results.
This allows you to configure a cloud-to-cloud file workflow that directly transfers files stored in AWS to the Azure environment and connects subsequent processing and operational checks, without going through a local PC or intermediate storage server.
Developer#
After registering the source and target storage as devices, specify prefixes to create the transfer and check the terminal status. Prepare the following items before starting.
| Requirement | Details |
|---|---|
| INNORIX Authentication | INNORIX_ACCESS_TOKEN (Authorization: Bearer) |
| Source S3 Device | Device ID of the S3 bucket and source prefix (e.g., media/2026/09) |
| Target Azure Device | Device ID of the Azure Blob container and target prefix (e.g., archive/2026/09) |
| Runtime | Python 3 + requests, Java 17+, Node.js 18+, .NET 8+ |
Python and Node.js reuse the minimal
api()helper that directly calls REST and the status constants (STATUS_COMPLETE,TERMINAL) from the API Call Recipe. Java and C# use the bundled-sourceInnorixClient(including constants) andJsonhelper (Jfor C#). Replace the device identifiers (s3-src,azure-dst) and prefixes with actual values.
Create S3 → Azure Blob Transfer#
Use the prefix as the folder root (sourcePaths + sendAllFolder) to create the transfer. Set target-action to overwrite so an object with the same target key in the target prefix is overwritten. After creating the transfer, check the terminal status using monitorId.
import time


def transfer_objects(source, target, prefixes, target_prefix, action="overwrite"):
    transfer = api("POST", "/api/transfers/manual", {
        "sourceDevice": source,
        "targetDevice": target,
        "targetPath": target_prefix,
        "sourcePaths": prefixes,
        "sendAllFolder": True,
        "transferOptions": {"target-action": action},
    })
    return transfer["monitorId"]


def wait_transfer(monitor_id, timeout=14400, interval=5):
    deadline = time.time() + timeout
    while time.time() < deadline:
        detail = api("GET", f"/api/transfers/{monitor_id}") or {}
        if detail.get("status") in TERMINAL:
            return detail
        time.sleep(interval)
    raise TimeoutError(monitor_id)


monitor_id = transfer_objects("s3-src", "azure-dst", ["media/2026/09"], "archive/2026/09")
detail = wait_transfer(monitor_id)
print("completed:", detail.get("status") == STATUS_COMPLETE)
static String transferObjects(InnorixClient client, String source, String target,
List<String> prefixes, String targetPrefix, String action) {
Map<String, Object> transfer = client.apiObj("POST", "/api/transfers/manual", Json.newObj(
"sourceDevice", source,
"targetDevice", target,
"targetPath", targetPrefix,
"sourcePaths", prefixes,
"sendAllFolder", true,
"transferOptions", Json.newObj("target-action", action)), null);
return Json.str(transfer, "monitorId");
}
static Map<String, Object> waitTransfer(InnorixClient client, String monitorId,
long timeoutSec, long intervalSec) throws InterruptedException {
long deadline = System.currentTimeMillis() + timeoutSec * 1000;
while (System.currentTimeMillis() < deadline) {
Map<String, Object> detail = client.apiObj("GET", "/api/transfers/" + monitorId, null, null);
Integer status = Json.intOrNull(detail, "status");
if (status != null && InnorixClient.TERMINAL.contains(status))
return detail;
Thread.sleep(intervalSec * 1000);
}
throw new RuntimeException("timeout: " + monitorId);
}async function transferObjects(source, target, prefixes, targetPrefix, action = "overwrite") {
const transfer = await api("POST", "/api/transfers/manual", {
sourceDevice: source,
targetDevice: target,
targetPath: targetPrefix,
sourcePaths: prefixes,
sendAllFolder: true,
transferOptions: { "target-action": action },
});
return transfer.monitorId;
}
async function waitTransfer(monitorId, { timeout = 14400, interval = 5 } = {}) {
const deadline = Date.now() + timeout * 1000;
while (Date.now() < deadline) {
const detail = (await api("GET", `/api/transfers/${monitorId}`)) || {};
if (TERMINAL.has(detail.status)) return detail;
await new Promise((r) => setTimeout(r, interval * 1000));
}
throw new Error(`timeout: ${monitorId}`);
}
const monitorId = await transferObjects("s3-src", "azure-dst", ["media/2026/09"], "archive/2026/09");
const detail = await waitTransfer(monitorId);
console.log("completed:", detail.status === STATUS_COMPLETE);static async Task<string> TransferObjectsAsync(InnorixClient client, string source, string target,
IEnumerable<string> prefixes, string targetPrefix, string action = "overwrite")
{
var transfer = await client.ApiObjAsync("POST", "/api/transfers/manual", new JsonObject
{
["sourceDevice"] = source,
["targetDevice"] = target,
["targetPath"] = targetPrefix,
["sourcePaths"] = J.ArrOfStrings(prefixes),
["sendAllFolder"] = true,
["transferOptions"] = new JsonObject { ["target-action"] = action },
});
return J.Str(transfer, "monitorId");
}
static async Task<JsonObject> WaitTransferAsync(InnorixClient client, string monitorId,
int timeoutSec = 14400, int intervalSec = 5)
{
DateTime deadline = DateTime.UtcNow.AddSeconds(timeoutSec);
while (DateTime.UtcNow < deadline)
{
JsonObject detail = await client.ApiObjAsync("GET", quot;/api/transfers/{monitorId}", null, null);
int? status = J.IntOrNull(detail, "status");
if (status != null && InnorixClient.Terminal.Contains(status.Value))
return detail;
await Task.Delay(intervalSec * 1000);
}
throw new TimeoutException(monitorId);
}Overwrite Behavior When
numberingis used, an object with the same name at the target may be renamed. Useoverwriteto overwrite and update the object at the specified target key.
Target Prefix Path Azure Blob uses virtual paths under a container as prefixes. Specify the target prefix according to how the container is registered. For containers with many objects, splitting them into multiple transfers by prefix makes the scope of each transfer clear and helps narrow down failure points.
If failed objects remain, use retry_failed from the Stop and Resume Recipe (GET /api/transfers/{id}/files → POST /api/transfers/{id}/retry) to retransfer only the failed items.
Implementation Result#
Applying this recipe allows you to transfer objects from S3 to Azure Blob using the following flow.
- Amazon S3 (s3-src)Specify Prefix
- Create Transfer (overwrite)
- Wait for Terminal Status
- Azure Blob (azure-dst)Apply Objects to Target Prefix
- Retry Failed Objects Only
Run an S3 → Azure Blob transfer using only device IDs without handling cloud credentials in code, and selectively resend only the remaining failed objects.